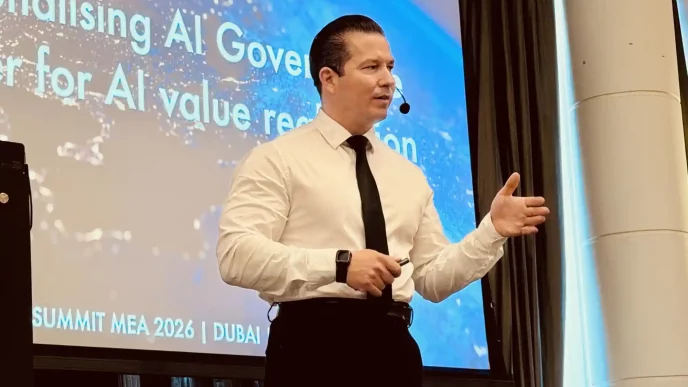
How can massive, slow-moving enterprise data lakes connect effectively with fast, low-latency AI applications? That was the core question addressed by Stan Polyakov, Machine Learning specialist at Nordic logistics company Instab (known for Instabox), during his presentation „From Historical Insight to Instant Retrieval: Forging the Link Between Data Lakes and AI Applications“ at the Nordic Data Science & Machine Learning (NDSML) Summit in Stockholm.
Delivering millions of parcels annually across Europe requires real-time precision. Like most enterprises, Instab faced a familiar dilemma: data lakes built on Apache Iceberg and Parquet software formats are optimized for long-term batch analytics, not real-time AI retrieval.
The session tackled why standard AI architectures break down at scale and provided a blueprint for building an integrated data-to-AI stack.
The Hidden Bottleneck of Standard RAG Systems
Retrieval-Augmented Generation (RAG) is widely seen as the go-to architecture for querying internal data. Standard RAG embeds a user’s prompt as a single vector, matches it against vector storage, and feeds relevant documents into a Large Language Model (LLM).
However, while building a RAG prototype takes minutes, moving to production reveals critical mathematical and structural limitations:
- Vector Averaging Errors: When queries involve complex choices (e.g., “Find reports on Option A or Option B”), embedding models average the semantic meaning across tokens. This dilutes precision, returning generic documents rather than exact matches.
- Vector Space Overcrowding: As a document repository expands from hundreds to tens of thousands of files, nearest-neighbor vector searches become noisy, returning irrelevant context.
- Inability to Handle Structured Data: LLMs relying solely on semantic vector search struggle with quantitative queries, such as exact Q3 revenue figures or filtered aggregations.
Recent DeepMind research demonstrates that single-vector embeddings face hard mathematical bounds, regardless of dimension size, a single vector cannot resolve all complex queries. 
Moving Beyond Naive Retrieval: A Holistic 3-Layer Stack
To overcome these barriers, enterprise systems should think about treating data access as a multi-layered architecture rather than a quick patch on a vector database.
1. The Smart Retrieval Layer
Instead of relying on a single query string, advanced retrieval techniques diversify context:
- Query Augmentation & RAG Fusion: Generating multiple related prompts to broaden relevant retrieval.
- Hypothetical Document Embeddings (HyDE): Prompting the LLM to write a hypothetical answer first, then retrieving files that resemble that candidate document.
- Multi-Vector Models (ColBERT): Assigning embeddings to individual tokens rather than entire sentences to preserve fine-grained precision.
2. The Factual Data Layer & Smart Orchestration
To prevent hallucinations on exact facts, systems can use the option to convert conceptual inquiries into structured queries:
- Tool Calling & SQL Generation: Automatically drafting SQL queries against data lake schemas for precise numeric calculations.
- Entity Extraction Pipelines: Running lightweight LLMs over incoming semi-structured text (like customer support tickets) to populate structured SQL tables for fast, verifiable querying.
- Custom Open-Source Query Engines: Moving beyond heavy, high-latency engines toward modular architectures like Apache Data Fusion for embedded, low-latency execution.
3. The Storage & Memory Optimization Layer
Optimizing the underlying storage drastically cuts latency before data reaches the LLM:
- Metadata & Parquet Tuning: Utilizing footer metadata inside Parquet files to enable rapid data skipping.
- Liquid Caching: Inserting high-speed caching layers between compute engines and object storage (like AWS S3).
- Incremental View Maintenance (IVM): Continuously updating materialized views using tiny data deltas rather than recalculating entire datasets from scratch.
From Concept to Code
While aligning these three layers establishes the foundation for high-performance AI applications, mastering the underlying engineering mechanics requires a deeper look into the specific benchmarks, implementation trade-offs, and research papers behind these patterns.
This overview scratches the surface. In the complete presentation, Polyakov breaks down specific research papers from DeepMind and Meta, offers code-level architectures for Apache Data Fusion, and explores cutting-edge data formats embedding WebAssembly (Wasm) runtimes directly inside storage files.
Access the Full Session Video: Unlock Polyakov’s complete presentation and hundreds of other enterprise AI engineering talks by accessing the official NDSML Summit Video Archive.
Join the Next NDSML Summit
Ready to explore production-ready AI systems, agentic workflows, and real-world enterprise architectures live?
Join leading AI practitioners, data engineers, and ML researchers in Stockholm for the next edition of the Nordic Data Science & Machine Learning Summit.
- Dates: November 10–11, 2026
- Location: Filadelfia Convention Center, Stockholm & Online
- Focus: Enterprise Applied Agentic AI, Data Engineering & Operational Trust