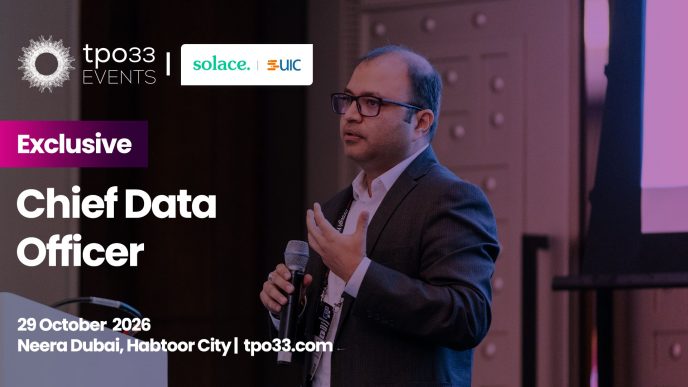
We sat down with Nishant Gupta, Staff Software Engineer and Researcher at Meta’s Superintelligence Lab, to discuss the reliability challenges of autonomous AI systems.
As AI workloads become increasingly autonomous, measuring CPU usage, latency, and uptime only covers half the equation. According to Nishant Gupta, Staff Software Engineer and Researcher at Meta’s Superintelligence Lab, building reliable AI infrastructure requires evaluating execution outputs, reasoning quality, and decision health in real time.
Having spent years building distributed compute systems across massive data center infrastructure, Nishant’s work focuses on a central challenge: building predictable, reliable systems for AI workloads that are inherently non-deterministic.
Ahead of his session at the upcoming NDSML Summit, Nishant breaks down why evaluation must become a first-class component of production observability, how to catch agent reasoning loops, and how to safely wire runtime feedback into automated recovery.
In your session at the NDSML Summit, you discuss why green observability dashboards lie. Why do traditional metrics like uptime miss AI quality failures?
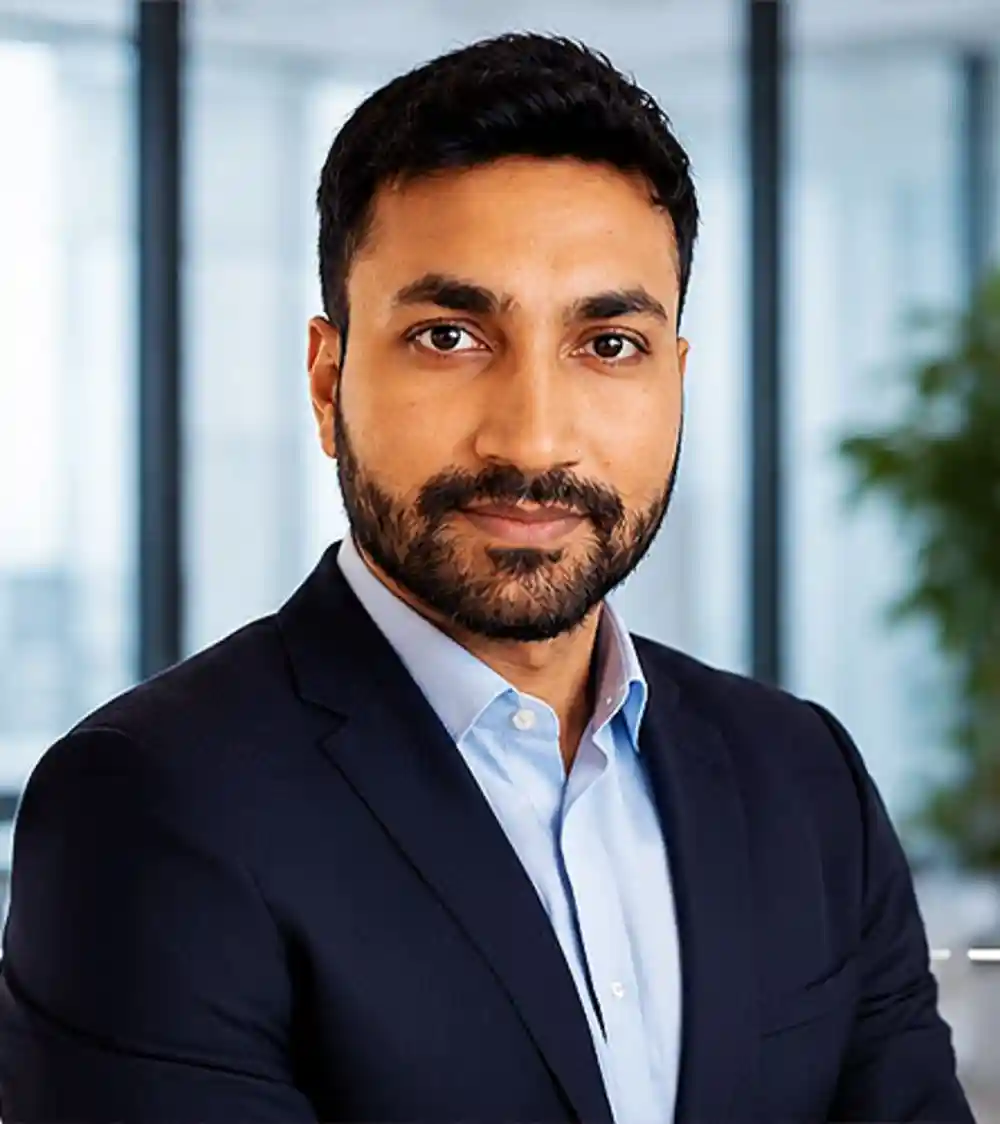
Traditional observability was designed around a relatively simple assumption: if your infrastructure is healthy, your application is probably healthy. We monitor CPU utilization, memory, latency, error rates, and availability. And those metrics are still important. But AI systems introduce an entirely new class of failures.
Imagine an AI agent that responds in 200 milliseconds, returns HTTP 200, and operates with 99.99% availability. From an infrastructure perspective, everything looks perfect. 
But what if that agent confidently provides incorrect information, retrieves the wrong documents, or makes a decision that violates business rules? Your dashboard is green, but your system is failing.
The fundamental problem is that traditional observability measures whether a system executed successfully, not whether it achieved the correct outcome. With AI, we need to extend observability beyond infrastructure health into semantic correctness, task completion, reasoning quality, and policy compliance.
That’s why I believe evaluation needs to become a first-class component of production observability, rather than something we only perform before deployment.
Why does moving from passive chatbots to active AI agents make that blind spot so much more critical to address?
The biggest difference is that we’re moving from systems that generate information to systems that take actions. A traditional chatbot might provide an incorrect answer. That’s certainly a problem, but in many cases, a human can recognize the mistake before acting on it.
An AI agent, however, might execute code, call APIs, modify databases, initiate transactions, or coordinate with other agents. Now an incorrect decision can produce real-world consequences.
For example, imagine an agent responsible for managing cloud infrastructure. It incorrectly interprets a performance signal and decides to terminate healthy compute instances. Every individual API call might succeed. The infrastructure metrics might remain green. But the agent has made a fundamentally wrong decision.
And the problem becomes even more significant with multi-agent systems, where one agent’s incorrect output can influence the decisions of several others. As AI systems gain more autonomy, correctness stops being just a quality concern and becomes a reliability and safety concern.
That’s why we need continuous evaluation, execution-level observability, and runtime guardrails before we can safely scale agent autonomy.
To catch those agent failures, you instrument the whole execution path. How do you distinguish a simple infrastructure glitch from an agent getting stuck in a loop?
The key is to stop treating an agent execution as a single request and instead observe it as a sequence of decisions and actions. In traditional distributed systems, distributed tracing helps us understand how requests move between services.
For AI agents, we need to extend that concept to capture model invocations, tool calls, intermediate decisions, retries, state transitions, and evaluation results. Let’s consider two scenarios. In the first, an agent calls an external API and receives a timeout. That’s likely an infrastructure or dependency failure. We can detect it through latency, error codes, and retry patterns. In the second, the agent repeatedly calls the same tool with nearly identical arguments, receives valid responses, but makes no meaningful progress toward its objective.
Infrastructure monitoring might report that everything is functioning normally. But execution-level monitoring reveals a reasoning or planning loop. We can detect that using signals such as repeated tool-call signatures, lack of state progression, excessive reasoning steps, and token consumption without corresponding task progress.
The important distinction is between execution health and decision health. And once we can observe both, we can apply different recovery strategies: infrastructure retries for transient failures, and replanning, model rerouting, or human escalation for agent-level failures.
Architecturally, how do you wire evaluation outputs into runtime feedback loops to safely trigger model rerouting or retries?
I think the most important architectural principle is to separate evaluation from recovery decisions. An evaluator should determine whether something is wrong, but it shouldn’t necessarily decide what action to take. I like to think about this architecture as three layers.
The first is the execution layer, where agents interact with models, tools, and external systems. The second is the evaluation layer, which continuously examines execution traces, tool outputs, task progress, and policy compliance. Some evaluations can be deterministic, while others might use model-based judges. The third is the control layer, which translates evaluation signals into recovery actions based on predefined policies.
For example, if a model response fails a structured-output validation, the control layer might retry with a corrected prompt. If repeated evaluations indicate poor answer quality, it might reroute to a different model.
But if an agent attempts a high-risk action, such as transferring funds or modifying production infrastructure, the system should enforce an explicit policy or require human approval. An important detail is that retries must be bounded and side-effect-aware. We cannot blindly replay actions that might already have succeeded.
The evaluator provides evidence, the control plane enforces policy, and the execution layer carries out the approved recovery. This separation makes the system more predictable, auditable, and safe to operate at scale.
From an architectural standpoint, how should teams balance real-time online checks with deeper offline evaluation?
I don’t think online and offline evaluations should compete with each other. They solve fundamentally different problems, and a reliable AI system needs both. Online evaluation operates directly in the execution path, so it needs to be fast, targeted, and relatively inexpensive.
For example, we can validate structured outputs, check tool permissions, detect repeated actions, enforce execution budgets, and verify important business constraints before an agent proceeds. These checks protect the system while it’s operating.
Offline evaluation, on the other hand, allows us to perform deeper analysis without affecting user-facing latency. We can replay production traces in a controlled environment, evaluate task completion, compare different models, run adversarial scenarios, and identify systematic failure patterns.
The interesting part is connecting the two. When production monitoring identifies a new failure pattern, we should turn that failure into a reproducible evaluation case.
Then we can use offline testing to improve the model, prompts, tools, or policies, and deploy those improvements back into production. Online evaluation protects today’s execution. Offline evaluation improves tomorrow’s system.
The goal is to build a continuous learning loop where production failures become measurable improvements rather than recurring incidents.
When you pair continuous evaluation with automated recovery, how does that change the way engineering teams think about system reliability?
I think it fundamentally changes what we mean by reliability. Historically, reliability engineering has focused on preventing infrastructure failures and recovering quickly when something breaks.
We measure availability, latency, error budgets, and mean time to recovery. But in agentic systems, the infrastructure can be perfectly healthy while the agent is making poor decisions.
So we need to expand reliability from simply keeping the system running to ensuring the system continues making acceptable progress toward its intended objective. Continuous evaluation gives us a way to detect when the system is deviating from that objective.
Automated recovery gives us a way to respond before those deviations become larger failures. For example, instead of waiting for an agent to exhaust its entire execution budget, we might detect that it’s repeatedly making the same unsuccessful tool calls and trigger replanning.
This introduces new reliability measures, such as task success rate, recovery success rate, policy violation rate, and the cost of successful task completion.
It also changes how we think about error budgets. We need to account not just for unavailable requests, but also for completed requests that produce incorrect or unsafe outcomes. The next generation of reliability engineering won’t just ask, ‘Is the system available?’ It will ask, ‘Is the system achieving the right outcome, and can it recover when it doesn’t?’
As agents handle more complex tasks, how do you see the boundary between self-healing systems and human oversight evolving?
I believe we’ll see AI systems become increasingly capable of diagnosing and recovering from routine failures autonomously. For example, if an agent encounters a transient API failure, it should be able to retry safely.
If a model consistently fails to produce a valid structured response, the system might reroute to another model. And if an execution strategy isn’t making progress, the agent might replan within predefined constraints. But I don’t believe every decision should be automated. The boundary should depend on the risk, reversibility, and consequences of an action.
Low-risk, reversible operations can be highly automated. High-risk or irreversible actions, particularly those involving financial transactions, sensitive data, security policies, or production infrastructure, need stronger safeguards and sometimes explicit human approval.
And importantly, human oversight shouldn’t mean asking a person to inspect every individual agent decision. That simply doesn’t scale. Instead, humans should define the policies, risk boundaries, and escalation conditions within which agents are allowed to operate. In other words, the future isn’t about removing humans from the loop. It’s about moving humans from supervising every action to governing the boundaries of autonomy.
That’s how I think we can build AI systems that are both highly autonomous and trustworthy.
Catch Nishant Gupta live at the upcoming NDSML Summit, where he will explore these architectural patterns in depth. If you’re attending, don’t miss his session on building reliable infrastructure for intelligent workloads.