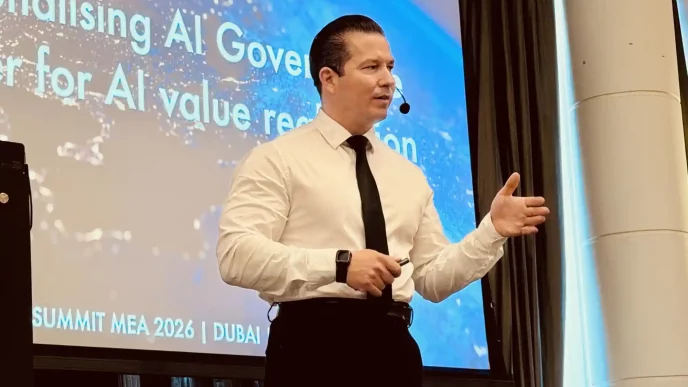
What does it take to scale AI safely without stifling innovation? We sat down with Mark Beckwith, Director of Data Governance and Architecture at the Financial Times, to find out.
Mark Beckwith has spent nearly 15 years at the Financial Times (FT) across multiple data roles, and in his current role as Director of Data Governance and Architecture, he focuses on treating data as a trusted, strategically valuable asset while keeping a direct line of sight between governance efforts and commercial value. As AI shifts from experimentation into everyday editorial and business operations, that foundation has become essential. Mark’s guiding principle is simple: good governance should make it easier to do the right thing, not harder to get things done.
Ahead of his session at the upcoming Data 2030 Summit, Mark breaks down why AI governance isn’t a standalone discipline, how to adapt traditional data pillars for probabilistic models, and how to set guardrails that protect corporate IP without strangling experimentation.
In your session title for the upcoming Data 2030 Summit, you describe AI governance as data governance with “more chaos and risk.” What do you mean by that, and why is addressing this specific risk profile essential for scaling AI safely?
I use that phrase deliberately because I think there’s a tendency to treat AI governance as something entirely new and separate from data governance. In reality, many of the fundamental challenges are the same. We’re still concerned with ownership, quality, transparency, access, security and accountability. The difference is that AI amplifies those challenges and introduces a level of unpredictability that traditional data governance wasn’t necessarily designed to handle.
With conventional data systems, we generally expect the same input to produce the same output. With generative AI, that’s not always the case. 
Outputs can be probabilistic, models can behave differently in different contexts, and risks can emerge that weren’t obvious during development. You also have additional dimensions to consider: hallucinations, bias, explainability, intellectual property, model drift, and increasingly the ability of AI systems to take actions rather than simply provide information. And of course, the speed of adoption is extraordinary. People can now build and deploy AI-powered solutions much faster than traditional governance processes were designed to accommodate. The chaos comes from that combination of speed, complexity and unpredictability. The risk comes from assuming our existing controls are sufficient without adapting them. If we want to scale AI safely, we need to move beyond governance as a one-off approval exercise. We need continuous oversight, proportionate controls and clear accountability throughout the AI lifecycle. The goal isn’t to eliminate all uncertainty, because that’s unrealistic. It’s to understand the risks, establish acceptable boundaries and create the confidence to innovate responsibly.
In your experience across the industry, what are the main risks when organizations try to manage AI governance as an isolated discipline rather than extending their existing data governance foundations?
I think the biggest risk is fragmentation. Many organisations are understandably keen to establish AI governance frameworks, committees and policies. But if those structures operate independently of existing data governance, security, privacy, architecture and risk management, you can end up creating additional complexity rather than reducing it. You might have one team governing data quality, another managing information security, and a separate AI governance function assessing model risks, without anyone having a complete view of how those things connect. That creates gaps in accountability, duplicated controls and potentially conflicting requirements.
There’s also a danger of overlooking the fundamentals. You can have a sophisticated AI governance framework, but if you don’t understand where your data comes from, who owns it, whether you’re entitled to use it, or whether it’s fit for purpose, you’re building on very shaky foundations. Another risk is that AI governance becomes overly focused on the technology itself, rather than the business outcomes and decisions that technology supports. An AI model doesn’t exist in isolation. It’s part of a wider ecosystem of data, people, processes and technology, and governance needs to reflect that. My view is that organisations should extend and adapt their existing governance capabilities, bringing in new expertise and controls where AI introduces genuinely new risks. That creates a more joined-up approach and, importantly, one that’s easier for the business to understand and adopt.
How do traditional data governance pillars, such as clear ownership, data quality, and accessibility, need to evolve when applied to the unpredictable nature of AI models?
I think the traditional pillars remain absolutely relevant, but we need to broaden how we interpret and apply them. Take ownership, for example. In traditional data governance, we’re typically identifying who is accountable for a dataset, a data product or a business domain. With AI, we need to think about accountability across the entire lifecycle, including the data, the model, the application and the decisions or actions it supports. And that accountability can’t stop when a model goes into production. Data quality is another interesting example. Traditionally, we focus on things like accuracy, completeness, consistency and timeliness. Those still matter enormously, but with AI we also need to consider representativeness, bias, suitability for the intended purpose and how data quality affects model behaviour. We also need to extend quality thinking to the outputs themselves. A model can be trained on high-quality data and still generate an inaccurate or inappropriate response.
Accessibility is equally important. We’ve spent years trying to make data more discoverable and accessible, but AI forces us to be more precise about what accessible actually means. Just because data is technically available doesn’t mean it should be used to train a model, included in a prompt or exposed through an AI-generated response. We need to think about usage rights, sensitivity, context and the potential for information to be combined or inferred in ways we hadn’t anticipated. So, for me, the evolution is from governing data as an asset to governing how data is used, interpreted and acted upon by intelligent systems. That’s a much broader responsibility, but it’s a natural progression of what good data governance has always been trying to achieve.
With those evolving pillars in mind, how do you design guardrails so they protect the organization without slowing down team experimentation?
I think the first principle is that governance needs to be proportionate to risk. Not every AI use case requires the same level of scrutiny. Someone using an approved AI tool to summarise a non-sensitive internal document presents a very different risk profile from an AI system making consequential decisions or interacting directly with customers. If we apply the same heavyweight governance process to everything, we’ll create frustration, slow innovation and potentially encourage people to work around the controls. Instead, we should establish clear, risk-based guardrails that allow low-risk experimentation to happen quickly, while introducing more rigorous assessment and oversight as the potential impact increases. The second principle is to make governance as easy to follow as possible. That means providing approved tools and environments, clear guidance on acceptable data usage, reusable architectural patterns and straightforward processes for assessing new use cases.
Where possible, controls should be embedded into the platforms and workflows teams already use, rather than relying entirely on manual reviews and approvals. The third principle is to distinguish experimentation from production. We should encourage teams to explore what’s possible in safe environments, with appropriate data protections and clear boundaries. But moving from an experiment to a live business capability should trigger a more structured assessment of risk, accountability, monitoring and operational readiness. And finally, governance needs to be collaborative. The governance function shouldn’t simply be the team that says yes or no. It should work alongside engineering, product, security, legal and business teams to help them achieve their objectives safely.
Putting those guardrails into practice at the Financial Times, what traditional data policy adapted most naturally to AI, and where did the team have to innovate most?
I think one of the most natural extensions of existing policy is around the protection and responsible use of our intellectual property. At the FT, this is particularly important because of the value of both the content we create and the data we produce. Whether that’s our journalism, proprietary datasets, research or the insights we generate, we need to be clear about how those assets can be accessed, used, shared and ultimately protected. The underlying governance principles in this area aren’t new. We’ve always needed to understand what information we hold, who owns it, what rights are associated with it and what people are permitted to do with it. But AI introduces a whole new dimension to those questions. For example, having legitimate access to a piece of content or a dataset doesn’t automatically mean you have the right to use it to train or fine-tune an AI model, share it with a third-party AI provider or make it available through an AI-powered product. And it’s not just about protecting what goes into an AI system.
We also need to think about what comes out of it. Could an AI-generated response reproduce valuable proprietary content? Could it expose commercially sensitive data or effectively recreate something that would ordinarily sit behind a licence or subscription? I think that’s where traditional governance needs to evolve most. Historically, we’ve been quite focused on controlling access to information. With AI, we increasingly need to govern how our intellectual property is used, transformed and potentially redistributed, often in ways that are much harder to predict or control. And there’s an important balance to strike. We don’t want to protect our intellectual property so restrictively that we prevent ourselves from unlocking its value through AI. Equally, we can’t assume that because something is technically possible, it’s commercially or legally appropriate. For me, the biggest shift is from simply governing who can access our content and data, to governing what AI systems are permitted to do with those assets, and how we retain control over the value they create.
Looking toward 2030, how must governance leaders rethink traditional concepts of accountability and data ownership as AI systems become increasingly autonomous?
I think this is going to be one of the most significant challenges for governance leaders over the next few years. Traditionally, accountability has been relatively straightforward to describe. We identify a data owner, a system owner or a business process owner, and establish their responsibilities. But as AI systems become more autonomous, the relationship between human decisions and system actions becomes more complex. We’re moving towards a world where AI systems won’t just analyse information or recommend actions. They’ll increasingly be able to plan, make decisions, interact with other systems and execute tasks with limited human intervention.
That raises some fundamental questions. Who is accountable when an AI agent makes a decision? How do we ensure it operates within its intended authority? And how do we maintain meaningful oversight when the speed and volume of automated actions exceed what humans can review individually? I don’t think the answer is to make AI systems accountable in the same way as people. Accountability must remain with identifiable humans and organisations, even when execution is increasingly autonomous. What needs to change is how we design and demonstrate that accountability. We’ll need clearer ownership of AI-enabled business outcomes, explicit boundaries around what autonomous systems are authorised to do, and much stronger capabilities for monitoring, traceability, intervention and audit.
I also think the concept of data ownership will need to become more connected to usage rights and decision authority. It won’t be enough to know who owns the underlying data. We’ll need to understand which systems can use it, for what purposes, what decisions they can make, and under whose authority. And governance will increasingly need to be built into the technology itself. We simply won’t be able to govern highly autonomous systems through policies, spreadsheets and committees alone. Looking towards 2030, I think the most successful governance leaders will be those who can combine strong foundational principles with much more adaptive, automated and embedded controls. Ultimately, the challenge isn’t to govern AI as though it were human. It’s to ensure that, however autonomous our technology becomes, human accountability, trust and control remain firmly in place.
Join Mark Beckwith, at the upcoming Data 2030 Summit to learn how to adapt your existing data pillars, set risk-based guardrails, and scale AI safely without slowing down innovation.